TL;DR: Reflection AI published the weights for Beam, its first open-weight model (501B total / 23B active parameters), on 16 October 2026 under the Apache 2.0 license. Hosted inference starts at $0.25 per 1M input tokens (OpenRouter) with $1.00 per 1M output — roughly one-sixth the session cost of GLM-5.2 and one-fourteenth of Kimi K3. Independent tests rank it #2 among US open-weight models on the Artificial Analysis Intelligence Index (score 30), with strong agentic-coding scores but weak terminal-coding scores (3.0%). It is not on tokens.bd yet (checked 17 October 2026).
What changed on 16 October 2026#
Beam itself was announced on 5 October 2026, but only as early access behind a waitlist — the weights were promised "later in the month." On 16 October, Reflection kept that promise:
- The full weights landed on Hugging Face as
reflection/Beam-1.0-501B-A23B, in BF16, FP8, and NVFP4 formats, plus a speculative-decoding drafter model. - License: Apache 2.0 — download, fine-tune, self-host, and ship commercially with no seat or usage limits.
- Beam is a text-only mixture-of-experts model: 501 billion total parameters, 23 billion active per token, 1 million token context, knowledge cutoff 30 June 2026.
- Reflection says it pretrained Beam on 23.8 trillion tokens and ran more than 100 million reinforcement-learning rollouts on 10,500 NVIDIA GB300 GPUs over four weeks.
- Reflection also opened a public beta of its first-party API at platform.reflection.ai, "free to start."
- The company open-sourced Mirror CLI, a terminal agent harness it built for internal engineering use: resumable conversations, parallel agents in separate worktrees, MCP connections, and integrations with Slack, Linear, and GitHub.
Day-0 framework support is unusually broad: Hugging Face Transformers, vLLM, SGLang, Unsloth, Axolotl, TokenSpeed, and NVIDIA Dynamo. Like the models in our reasoning effort guide, Beam exposes an adjustable reasoning-effort parameter — lower settings for shorter responses, higher settings for harder reasoning.
What it costs: hosted prices checked 17 October 2026#
You don't need your own GPU cluster. Two public hosted prices are confirmed today:
| Provider | Input / 1M | Cached input / 1M | Output / 1M | Notes |
|---|---|---|---|---|
OpenRouter (reflection/beam-1.0-501b-a23b) | $0.25 | — | $1.00 | Routed across Nebius, Together, CoreWeave, Baseten |
| Baseten Model APIs | $1.30 | $0.13 | $4.30 | Day-0 support, dedicated inference available |
| Reflection API (beta) | free to start | — | — | Public beta at platform.reflection.ai |
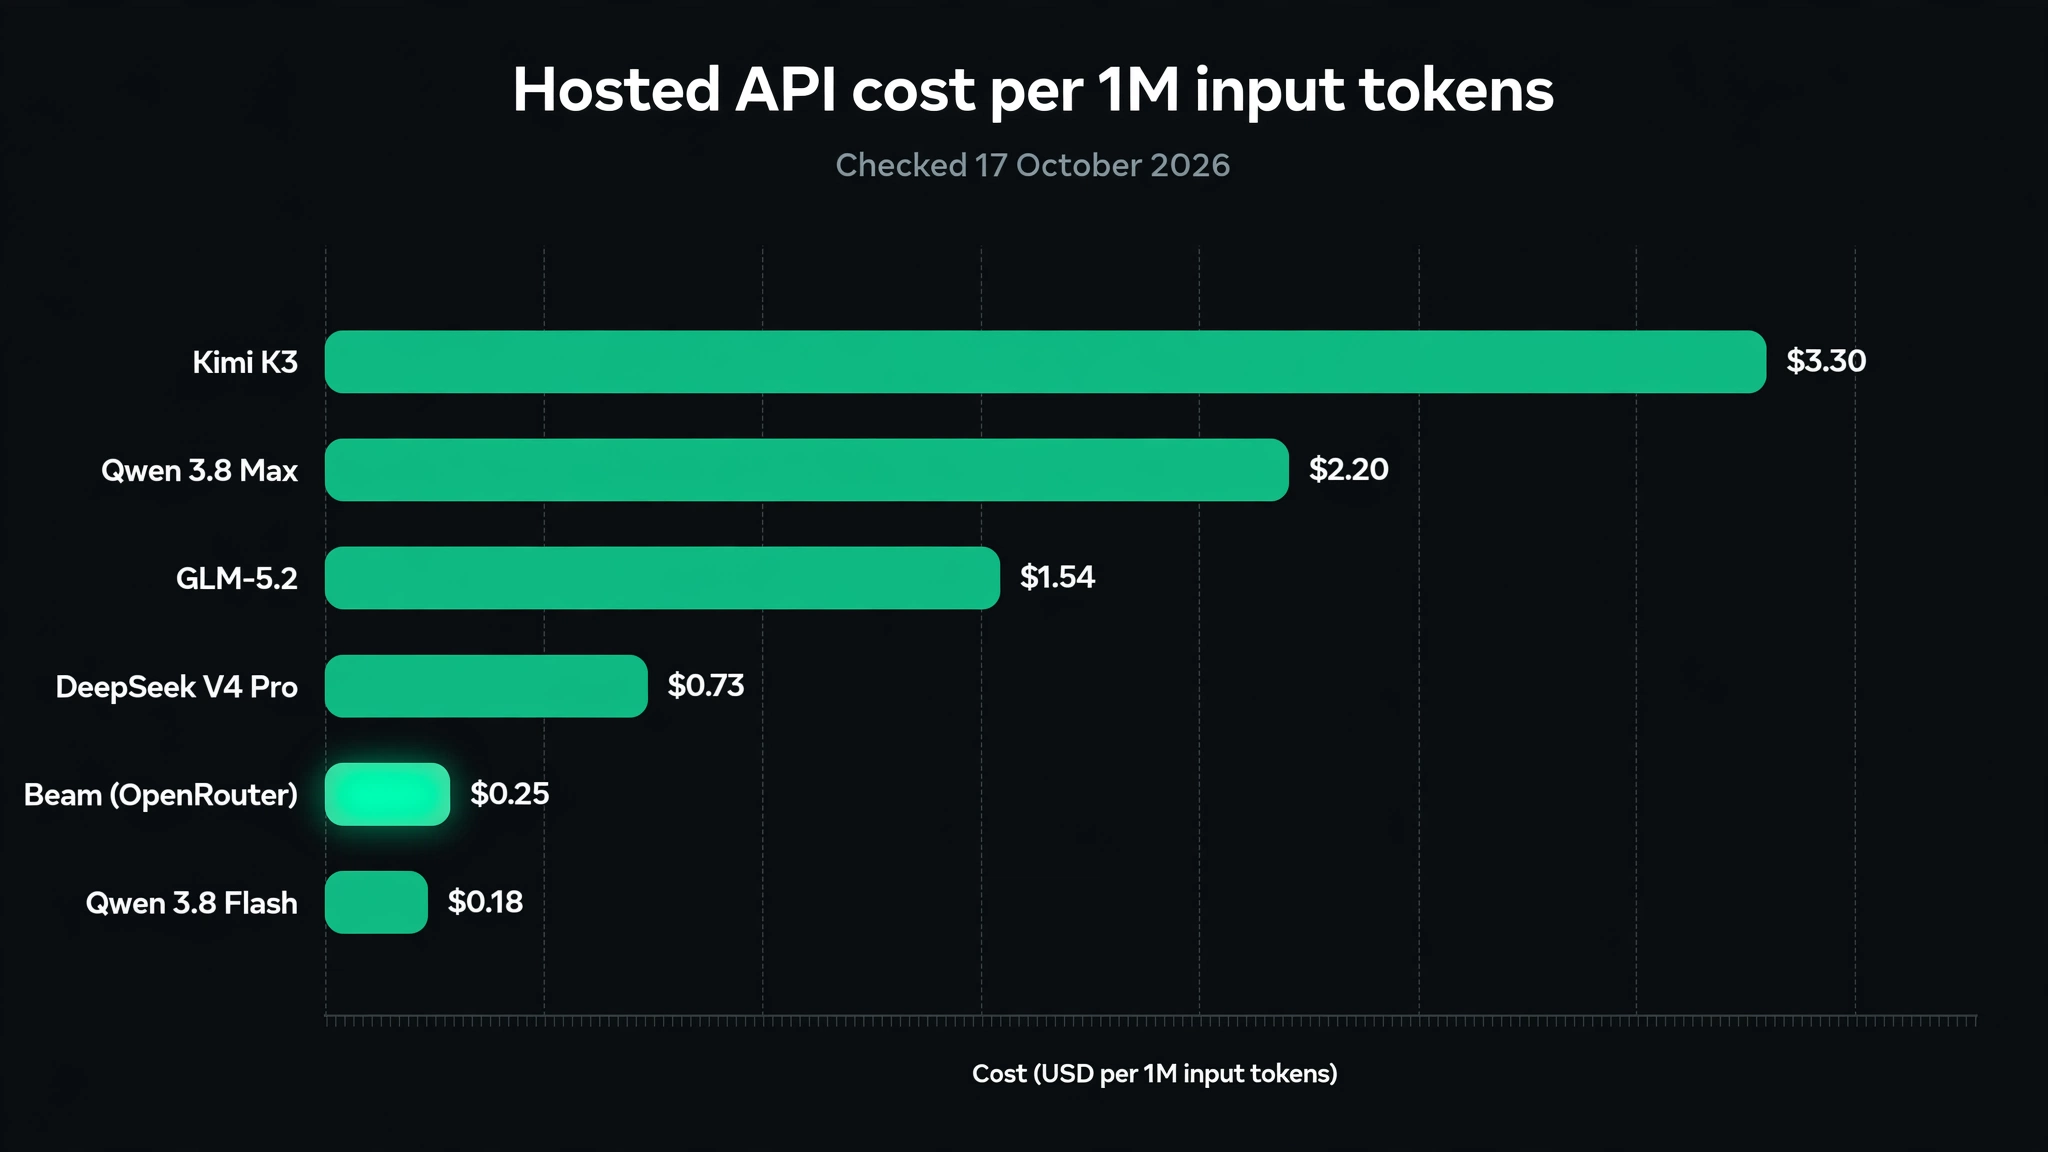
How does that sit against Beam's capability peers on the tokens.bd catalog (prices checked 17 October 2026)?
| Model | Input / 1M | Output / 1M |
|---|---|---|
| Beam (OpenRouter) | $0.25 | $1.00 |
| DeepSeek V4 Pro | $0.73 | $2.18 |
| GLM-5.2 | $1.54 | $4.84 |
| Qwen 3.8 Max | $2.20 | $6.60 |
| Kimi K3 | $3.30 | $16.50 |
Beam's input price is roughly one-thirteenth of Kimi K3's ($0.25 vs $3.30). The gap is smaller than the headline Haiku-5.5-style price cuts, but it applies to a 501B-parameter agentic model, not a small fast one.
Worked example: a real agentic session at each price#
Take a heavy agentic session — 500K input tokens, 50K output tokens — and price it per the tables above. Currency: ৳123.00/USD (mid-market rate, checked 17 October 2026).
| Model | Input cost | Output cost | Session total | In BDT |
|---|---|---|---|---|
| Beam (OpenRouter) | 0.5 × $0.25 = $0.125 | 0.05 × $1.00 = $0.05 | $0.175 | ৳21.53 |
| DeepSeek V4 Pro | 0.5 × $0.73 = $0.365 | 0.05 × $2.18 = $0.109 | $0.474 | ৳58.30 |
| GLM-5.2 | 0.5 × $1.54 = $0.77 | 0.05 × $4.84 = $0.242 | $1.012 | ৳124.48 |
| Qwen 3.8 Max | 0.5 × $2.20 = $1.10 | 0.05 × $6.60 = $0.33 | $1.43 | ৳175.89 |
| Kimi K3 | 0.5 × $3.30 = $1.65 | 0.05 × $16.50 = $0.825 | $2.475 | ৳304.43 |
The same session costs about one-sixth of GLM-5.2 ($0.175 vs $1.012) and about one-fourteenth of Kimi K3 ($0.175 vs $2.475). And Beam has a second cost lever: Artificial Analysis measured Beam at roughly 26K output tokens per Intelligence Index task versus ~52K for K2 Horizon — about half the tokens for a point more intelligence. Half the tokens at one-sixth the per-token price compounds fast on long agent runs.
Benchmarks: independent tests vs company claims#
Two things are true at once: Reflection's own numbers are strong, and independent verification is thin so far. Label accordingly.
Independent — Artificial Analysis (17 October 2026):
- Intelligence Index: 30 — #2 among US open-weight models, behind Meta's Muse Spark Open (39) and ahead of NVIDIA's Nemotron 3.5 Super VL (26).
- AutomationBench-AA: 48.5% — well ahead of K2 Horizon (37.2%), level with Qwen 3.8 27B (48.2%). Genuinely strong agentic-coding.
- Terminal-Bench 4.0: 3.0% — the weak spot, behind Qwen 3.8 27B (5.6%) and Muse Spark Open (8.1%). If your work is heavy terminal scripting, note this.
- Knowledge breadth vs hallucination: 33% of questions answered correctly (ahead of peers) but a 47% hallucination rate — know more, guess more.
Company-published (Reflection, via Baseten's launch post):
- SWE-bench Verified 80.9%, GPQA Diamond 90.5%, AIME 2026 97.8%, Terminal-Bench v2.1 80.1%, MCP Atlas 78.7%.
- Head-to-head with GLM-5.2: SWE-Bench Pro v1 65.5 vs 62.1, GPQA Diamond 90.5 vs 91.2, Terminal-Bench v2.1 80.1 vs 81.0, Humanity's Last Exam (no tools) 36.2 vs 40.5.
- Reflection's headline claim remains the one from launch: matches GLM-5.2-class reasoning at 3–4× less inference compute, trained with a length penalty that rewards correct answers in fewer tokens.
For context on the whole open-weight landscape, our best free open-weight models guide covers what to run on your own hardware — Beam now joins that list, with the hardware math below.
Should you switch? A quick decision tree#
Switch now if:
- You want Apache 2.0 freedom — fine-tune and sell commercially with no usage-tier limits. Meta's Muse Spark Open (released 15 October, AA score 39) is the stronger US open model on paper, but its Muse Model License carries commercial-use limits; Beam's Apache 2.0 has none.
- Your workload is long-horizon agentic work (multi-step tool use, code review, repo exploration) where Beam's 48.5% AutomationBench-AA score and token efficiency matter most.
- You need a US-origin open-weight model for procurement or policy reasons.
- You're price-sensitive: $0.175 for a 500K/50K session is the cheapest rate in its capability class today.
Hold off if:
- Your work is terminal-heavy — Artificial Analysis's 3.0% Terminal-Bench 4.0 score is a genuine red flag.
- You need multimodality — Beam is text-only; Muse Spark Open handles text, image, video, and audio.
- You want one API key with local payment — Beam is not on tokens.bd yet (checked 17 October 2026); the nearest catalog options are GLM-5.2, Kimi K3, and Qwen 3.8 Max.
How to use Beam today#
Option 1 — Hosted API via OpenRouter (OpenAI SDK, one line change):
from openai import OpenAI

client = OpenAI(
    base_url="https://openrouter.ai/api/v1",
    api_key="YOUR_OPENROUTER_KEY",
)

resp = client.chat.completions.create(
    model="reflection/beam-1.0-501b-a23b",
    messages=[{"role": "user", "content": "Refactor this module to remove the circular imports..."}],
)
Option 2 — Self-host from Hugging Face (day-0 Transformers support; rough memory needs: ~1 TB for BF16, ~500 GB for FP8, ~250 GB for NVFP4 — that's 501B parameters times the bytes-per-parameter):
from transformers import AutoModelForCausalLM, AutoTokenizer

model_id = "reflection/Beam-1.0-501B-A23B"
tokenizer = AutoTokenizer.from_pretrained(model_id)
model = AutoModelForCausalLM.from_pretrained(model_id, device_map="auto", torch_dtype="auto")
Option 3 — Reflection's own API, now in public beta and free to start, or Baseten Model APIs with day-0 support. Ollama and LM Studio are named launch partners, so consumer-friendly builds should follow.
FAQ#
Is Beam actually free? The weights are free under Apache 2.0 — download, fine-tune, self-host, and sell the result commercially with no usage limits. Hosted APIs still charge per token (from $0.25/1M input on OpenRouter), and running it yourself needs serious hardware. Reflection's own API beta is free to start.
Can I run Beam on a single GPU? No — not at full quality. 501B parameters need roughly 1 TB of memory in BF16, ~500 GB in FP8, or ~250 GB in NVFP4. Dedicated inference (e.g., Baseten) or a hosted API is the practical route; a 23B-active MoE still loads the full weight set.
How is Beam different from Meta's Muse Spark Open? Both are US open-weight MoE models released within 48 hours of each other (Spark Open on 15 October, Beam weights on 16 October). Muse Spark Open scores higher on the AA Intelligence Index (39 vs 30) and is multimodal, but ships under Meta's Muse Model License with commercial-use limits. Beam is text-only but fully Apache 2.0.
Is Beam available on tokens.bd?
Not yet — the catalog (checked 17 October 2026) does not list it. The closest catalog options for agentic coding are GLM-5.2, Kimi K3, and Qwen 3.8 Max on the model catalog. See the docs for the one-base_url-change pattern that works with any OpenAI-compatible API in the meantime.
What's the biggest risk with Beam right now? Two: its 3.0% Terminal-Bench 4.0 score (Artificial Analysis) suggests real weakness in terminal-heavy workflows, and most headline benchmark figures are still company-published rather than independently verified. Treat the first month as an evaluation period.
Prices, benchmark scores, and availability checked 17 October 2026. Hosted prices and model lists change; the provider's page is the authority for list prices.
Sources: Unite.AI — Reflection releases Beam's open weights under Apache 2.0 · OpenRouter — Beam 1.0 pricing & providers · Baseten — Beam model library · Artificial Analysis — Reflection has released Beam · Layer3Labs — Reflection AI explained · D-CSIL briefing — Beam efficiency analysis · Livemint — Meta Muse Spark Open launch