TL;DR: Claude Haiku 5.5 (launched 7 October 2026) and OpenAI's GPT-6 Luna (launched 22 September 2026) both list at $0.10/1M input and $0.50/1M output tokens — but both have price cliffs that re-price the whole request: Haiku at 100K tokens (5x), Luna at 272K (higher rate). On small agent calls they tie at about $0.0075 (৳0.92); on a 200K-token session Haiku costs 5x more than Luna. Haiku leads on published benchmarks; Luna wins on long-context value. Luna is available on Tokens today at $0.11/$0.55 — Haiku 5.5 isn't in the catalog yet. Prices checked 14 October 2026.
Two frontier labs now sell a capable small model for exactly the same price: $0.10 per million input tokens, $0.50 per million output tokens. Anthropic's Claude Haiku 5.5 arrived on 7 October 2026 with a headline "90% cheaper than Haiku 4.5"; OpenAI's GPT-6 Luna arrived on 22 September 2026 as the budget tier of the GPT-6 family. Same sticker, very different bill — because the price isn't the whole story. The context cliff, the tokenizer, and how much output each model burns to reach an answer move the real cost more than the headline rate.
We covered Haiku 5.5's launch in our price-cut breakdown. This post answers the question that post left open: which $0.10/1M model do you actually run your agents on?
Same sticker price, different bills#
List prices checked 14 October 2026, USD per million tokens.
| Claude Haiku 5.5 | GPT-6 Luna | |
|---|---|---|
| Input / output (standard tier) | $0.10 / $0.50 | $0.10 / $0.50 |
| Cached input reads | $0.01 | $0.01 |
| Price cliff | 100K tokens → 5x on the whole request ($0.50/$2.50) | 272K tokens → higher rate on the whole request |
| Context window | 1M | 1.05M |
| Max output | 128K | 128K |
| Effort control | 5 levels, default medium | none → max, default medium |
| Knowledge cutoff | — | 18 May 2026 |
| Launched | 7 Oct 2026 | 22 Sep 2026 |
Two things stand out. First, both cliffs re-price the entire request, not just the tokens past the line — cross the line and yesterday's cheap session costs 5x. Second, Luna's cliff sits nearly 3x higher than Haiku's, which is the single biggest practical difference between them for agent workloads with big context.
On Tokens, GPT-6 Luna is available today at $0.11/$0.55 per 1M as openai/gpt-6-luna — the closest cheap option in the catalog. Claude Haiku 5.5 is not yet in the Tokens catalog (checked 14 October 2026), so for now you call it through Anthropic directly; see the catalog for the current list of 60+ models.
Benchmarks: where each one wins#
Anthropic published head-to-head numbers against Luna at the Haiku 5.5 launch (vendor-reported — treat as directional, not gospel):
| Benchmark | Claude Haiku 5.5 | GPT-6 Luna |
|---|---|---|
| OSWorld 2.1 (computer use) | 72.4% | 48.9% |
| Terminal-Bench 4.0 | 39.2% | 16.4% |
| FrontierCode 1.1 | 46.4% | 42.4% |
| GDPval-AA v2.1 | 1620 | 1437 |
| AA-Briefcase v1.1 | 1578 | 1336 |
| Chartography | 46.4% | 29.1% |
Haiku 5.5 leads every row — but the independent check adds an asterisk. Artificial Analysis scores Haiku 5.5 at 43 vs Luna at 38 at max effort, while noting Haiku used about three times as many output tokens to get there. Output tokens are the expensive side of the price list ($0.50/1M), so Haiku's lead is real but partly paid for in tokens.
OpenAI's own Luna numbers tell a different, cost-flavored story: Luna scores 66.6% on DeepSWE at $0.22 per task and 50.9% on Agents' Last Exam at $0.15 per task — where its predecessor needed $2.57 per task for a comparable score. For bulk subagent work where cost per call matters more than the last few points, Luna's pitch is cost per finished task, not peak score.
Worked example: two agent sessions#
Prices checked 14 October 2026; FX ৳123.13 per USD. Arithmetic is exact from the list prices above.
Session A — small: 50K input + 5K output (both under their cliffs). A dead heat:
- Haiku 5.5: 0.05M × $0.10 + 0.005M × $0.50 = $0.0075 (~৳0.92)
- GPT-6 Luna: 0.05M × $0.10 + 0.005M × $0.50 = $0.0075 (~৳0.92)
- Luna on Tokens: 0.05M × $0.11 + 0.005M × $0.55 = $0.00825 (~৳1.02)
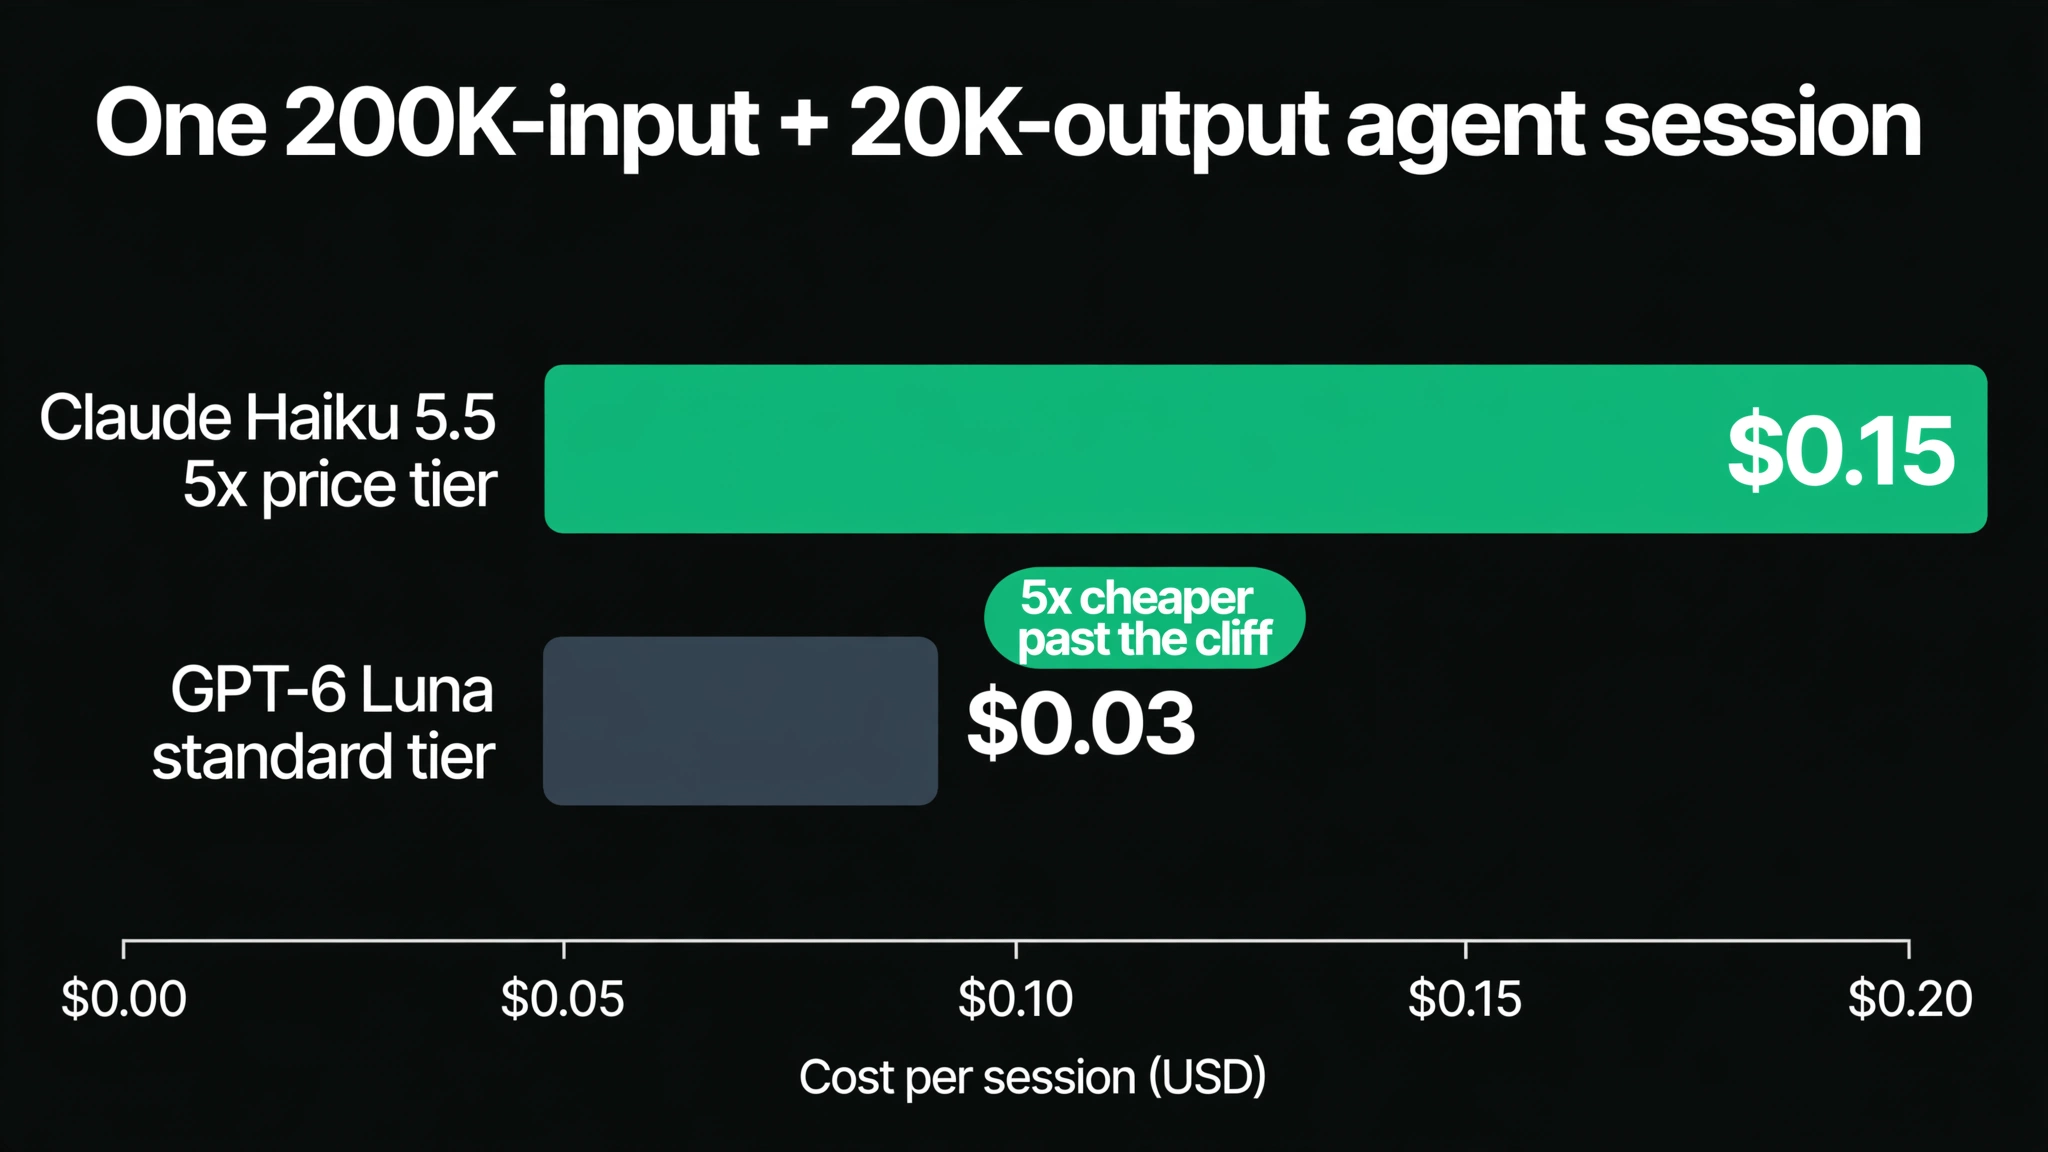
Session B — long context: 200K input + 20K output. Haiku crosses its 100K cliff (whole request at 5x); Luna stays under 272K:
- Haiku 5.5: 0.2M × $0.50 + 0.02M × $2.50 = $0.15 (~৳18.47)
- GPT-6 Luna: 0.2M × $0.10 + 0.02M × $0.50 = $0.03 (~৳3.69)
Same two models, same task shape — Haiku costs exactly 5x more on the long-context session purely because of where the cliffs sit. This is why the headline rate is the least interesting number on the price card.
The token-count fine print#
Two details inflate Haiku 5.5's real bill beyond the table:
- A new tokenizer. Independent testing found the same text counts as roughly 30% more tokens than on Haiku 4.5 — so "90% cheaper" is measured in per-token dollars, not in dollars per document. Anthropic itself puts the average saving at about 75%.
- Thinking is on by default. Haiku 5.5 reasons on every request unless you turn effort down, and thinking bills at the output rate. Combined with the ~3x output tokens noted in the independent benchmark, heavy agent loops should run Haiku at low or medium effort — not the default max.
Practical rule: keep Haiku's prompts under 100K tokens and its effort at medium or below, or the "cheapest Claude ever" quietly becomes the most expensive small model in your stack. The monthly bill estimator method works for this — model the cliff explicitly.
Which one for which job#
- Bulk subagent calls, extraction, summarization, classification → GPT-6 Luna. Dead-heat pricing on small calls, 5x cheaper past Haiku's cliff, and it's the one you can already call through Tokens with BDT payments.
- Computer use and terminal agents on a budget → Claude Haiku 5.5, if the vendor numbers hold. OSWorld 72.4% vs 48.9% and Terminal-Bench 39.2% vs 16.4% is a real gap for agentic desktop work — just keep sessions under 100K tokens.
- Hard coding → neither is the answer; that's Sonnet 5.5 / GPT-6.1 Sol territory, where Haiku-style models serve as the cheap first rung (see our price-cut breakdown).
Trying Luna on Tokens takes one line — the same base_url switch pattern works for every model in the catalog:
from openai import OpenAI

client = OpenAI(
    base_url="https://tokens.bd/v1",   # OpenAI-compatible gateway
    api_key="tkbd_your_key_here",
)

# GPT-6 Luna on Tokens: $0.11 in / $0.55 out per 1M (checked 14 Oct 2026)
resp = client.chat.completions.create(
    model="openai/gpt-6-luna",
    messages=[{"role": "user", "content": "Summarize this diff in 3 bullets."}],
    max_tokens=2000,
)
print(resp.choices[0].message.content)
Haiku 5.5 isn't routable through that key yet — when it lands in the catalog, the only change is the model string.
The Bangladesh angle#
At ৳123.13 per dollar, a small Luna agent call costs about ৳1 on Tokens — cheaper than the SMS it might replace. That changes the economics of student projects and indie SaaS: a 1,000-call-per-day background worker on Luna runs about ৳1,020/day (~৳30,600/month) at list math, payable in BDT through Tokens with no international card. Just watch Session B's lesson: one long-context loop crossing Haiku's cliff is ৳18.47 per call, and five of those a day add up faster than the headline rate suggests. Put long-context keys under per-key spend caps and let prompt caching eat the repeated context — both models cache reads at $0.01/1M.
Haiku 5.5 vs GPT-6 Luna FAQ#
Are Haiku 5.5 and GPT-6 Luna really the same price? On the standard tier, yes: $0.10/1M input and $0.50/1M output for both. The difference is where the standard tier ends — 100K prompt tokens for Haiku (then 5x on the whole request) vs 272K for Luna (then a higher rate). Real-world bills diverge on long-context work.
Which one is better at coding and agents? Anthropic's published numbers put Haiku 5.5 ahead on every shared benchmark (OSWorld 72.4% vs 48.9%, Terminal-Bench 39.2% vs 16.4%), but independent Artificial Analysis scoring narrows it to 43 vs 38 — with Haiku burning ~3x the output tokens to get there. Treat vendor benchmarks as directional.
Why does Haiku 5.5 cost more than the headline 90% saving suggests? Three reasons: prompts over 100K tokens re-price 5x on the whole request, the new tokenizer counts ~30% more tokens on the same text, and thinking is on by default at the output rate. Anthropic's own average-saving estimate is ~75%, not 90%.
Can I use both through Tokens?
GPT-6 Luna is in the catalog today (openai/gpt-6-luna, $0.11/$0.55 per 1M). Claude Haiku 5.5 is not in the catalog as of 14 October 2026 — use Anthropic directly for now.
What's the cheapest way to run agent loops on either? Keep prompts under the model's cliff (100K for Haiku, 272K for Luna), run effort at low/medium for routine turns, and cache repeated context — cached reads are $0.01/1M on both.
List prices checked 14 October 2026. Promotional prices and model defaults change; the maker's pricing page is the authority for list prices, and the model catalog for prices on Tokens.
Sources: Anthropic pricing · Anthropic's Haiku 5.5 launch benchmarks via Neowin · independent Haiku 5.5 cost/benchmark analysis · Haiku 5.5 in Claude Code — price tiers verified · GPT-6 Sol & Luna specs, pricing, benchmarks · GPT-6 Sol and Luna launch analysis · GPT-6 Sol/Luna guide with 272K cliff · USD/BDT rate 14 Oct 2026