TL;DR: Anthropic released Claude Haiku 5.5 on 7 October 2026 at $0.10 per million input tokens and $0.50 per million output tokens for prompts up to 100K tokens — a 90% list-price cut versus Haiku 4.5 that matches OpenAI's GPT-6 Luna. It also ships a 1M-token context window (up from 200K), 128K max output, and the first adjustable effort setting on a Haiku model. The same announcement halved Sonnet 5.5 cache reads ($0.20 → $0.10/1M) and added $100–500/month in API credits for Max and Team subscribers.
What changed: the new price list#
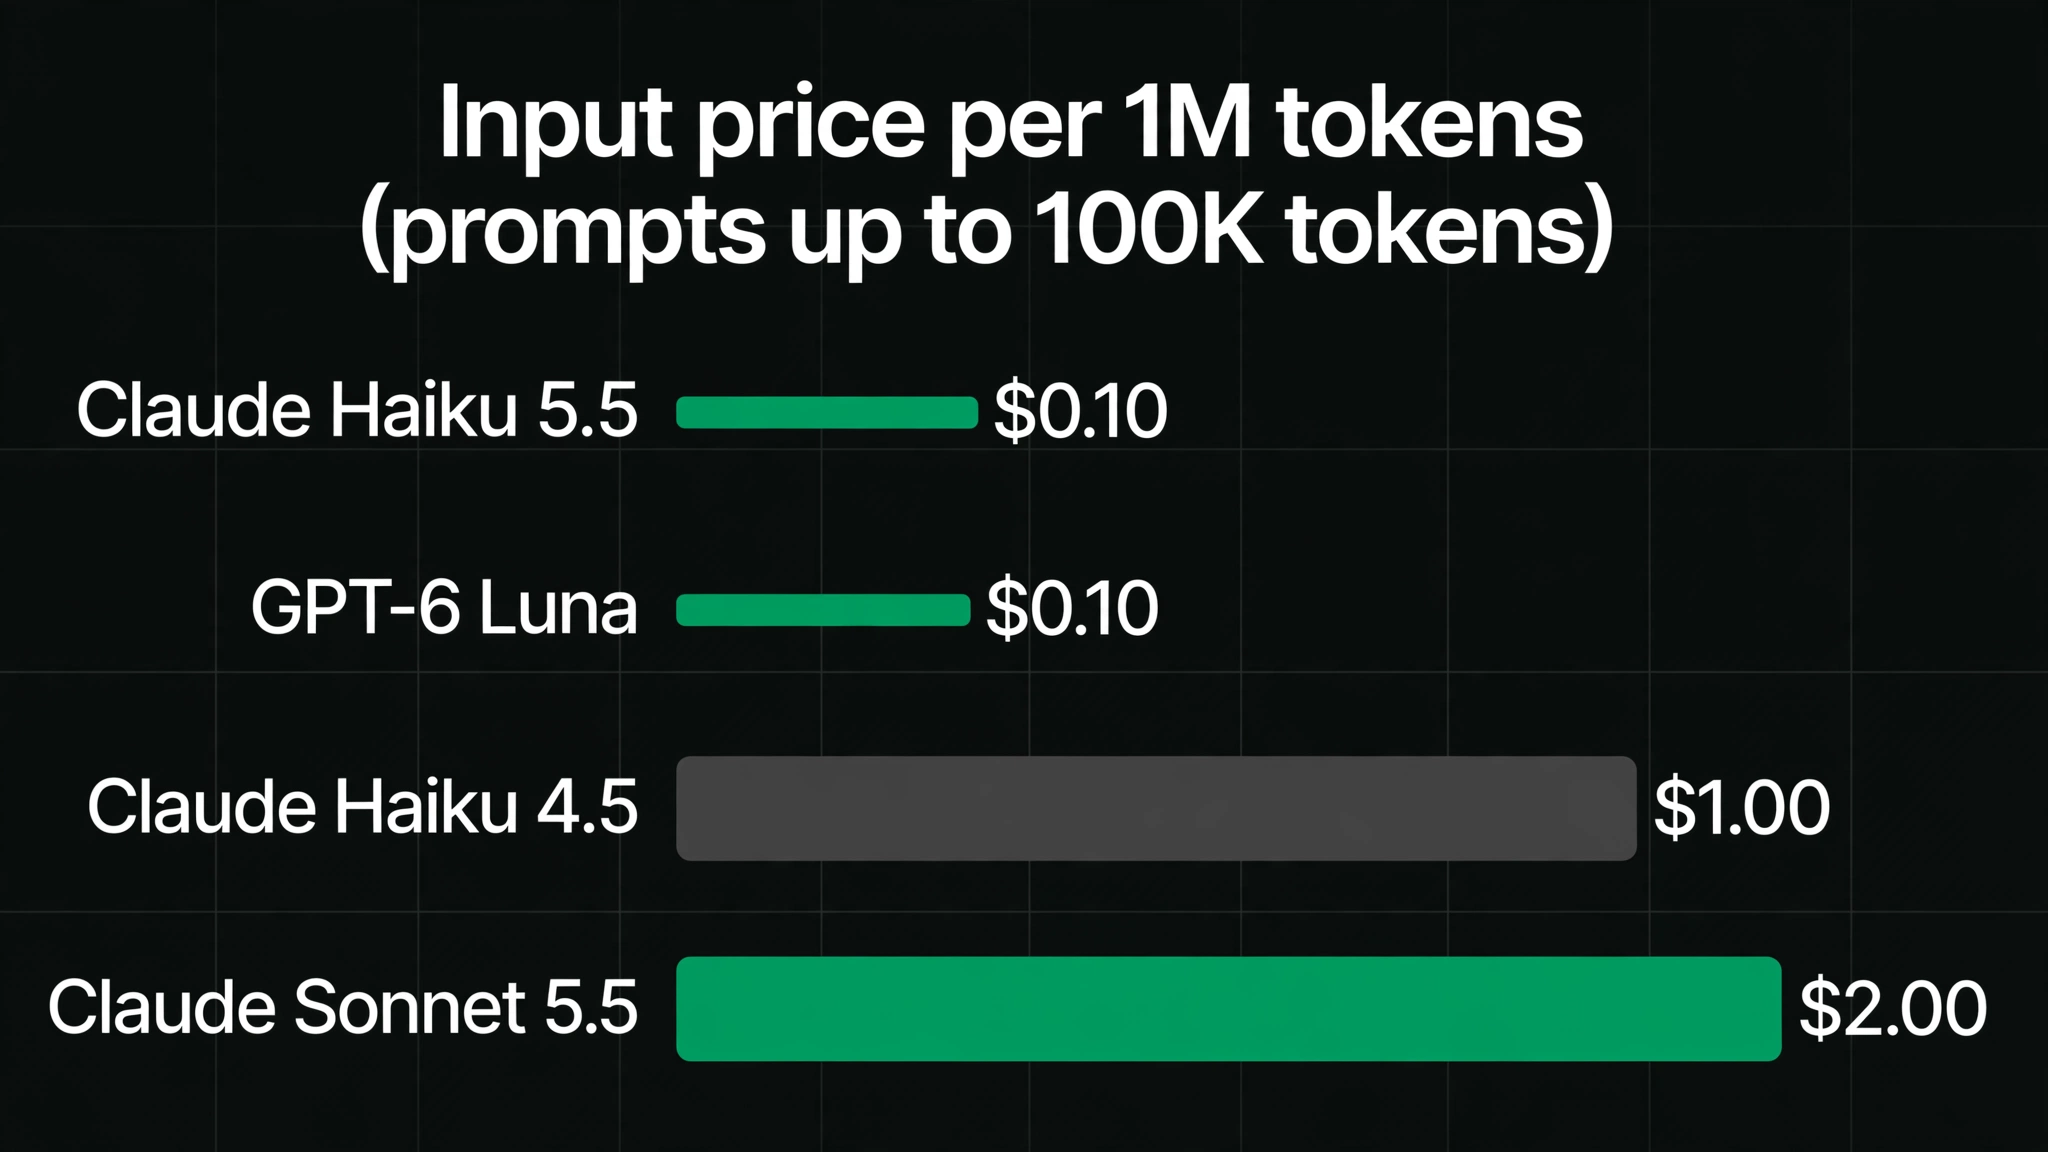
Anthropic priced Haiku 5.5 with two tiers keyed to prompt length — a structure that matters because, per Anthropic, roughly 90% of Haiku 4.5 requests fell under the 100K-token line, so most workloads pay the cheaper tier.
| Price per 1M tokens | Haiku 5.5 (prompts ≤ 100K) | Haiku 5.5 (prompts > 100K) | Haiku 4.5 | Sonnet 5.5 |
|---|---|---|---|---|
| Input | $0.10 | $0.50 | $1.00 | $2.00 |
| Output | $0.50 | $2.50 | $5.00 | $10.00 |
| Cache reads | $0.01 | $0.05 | $0.10 | $0.10 (was $0.20) |
| Cache writes (5-min) | $0.125 | $0.625 | $1.25 | $2.50 |
In BDT terms at the current rate (~৳123 per USD, 8 October 2026): one million input tokens on the cheap tier costs about ৳12, and one million output tokens about ৳62.
The headline "90% cut" is the per-token list-price drop for requests under 100,000 tokens. Anthropic's own "about 75% cheaper on average" figure is smaller because it reflects real workload mixes plus an updated tokenizer that uses slightly more tokens per task than Haiku 4.5's. Both numbers are true; the first is what you see on the price list, the second is closer to what your bill does.
The 100K cliff: the tier you actually pay#
The two-tier structure creates a cliff: one request over 100,000 tokens pays 5x the cheap-tier rates. Haiku 5.5's upper tier ($0.50/$2.50) is still 50% below Haiku 4.5's list prices, so it's not a punishment — but it is a design constraint for long-context workloads like context compaction, repo-wide summarization, and large retrieval prompts.
The practical responses, in order of payoff:
- Chunk the work. If a summarization job can run as ten 60K-token requests instead of one 600K-token request, it stays in the cheap tier.
- Cache the big context. Cache writes on the cheap tier are $0.125/1M, and cache reads are a penny per million — repeating the same long prompt is almost free once written. See prompt caching explained.
- Know where your 90th percentile is. If your P90 request is already over 100K tokens, budget at the upper tier and don't anchor on the $0.10 headline.
Benchmarks: is it still a "small" model?#
Anthropic published the following on launch day (7 October 2026). The usual caveat applies — these are vendor-published numbers — but the direction is clear: Haiku 5.5 is a large jump over Haiku 4.5, and on the one benchmark where both appear, it outscores GPT-6 Luna.
| Benchmark | Haiku 5.5 | Haiku 4.5 | GPT-6 Luna |
|---|---|---|---|
| GDPval-AA v2.1 (knowledge work) | 1620 | 735 | 1437 |
| AA-Briefcase v1.1 | 1578 | 614 | — |
| OSWorld 2.1 offline (computer use) | 72.4% | 15.7% | — |
| Terminal-Bench 4.0 (agentic coding) | 39.2% | 0.0% | — |
| FrontierCode 1.1 (Main) | 46.4% | — | — |
| Humanity's Last Exam | 45.9% (57.4% with tools) | 10.2% (18.7%) | — |
For reference, Sonnet 5.5 scores 1840 on GDPval-AA v2.1 — still well ahead, which is exactly Anthropic's positioning: Haiku is the fast, cheap worker tier (classification, summarization, extraction, subagent tasks, browser use), Sonnet and Opus remain the picks for complex agentic coding. The model ID is claude-haiku-5-5, live on the Claude Platform, AWS, Google Cloud, and Azure from launch day.
Adjustable effort: the dial comes to Haiku#
Haiku 5.5 is the first Haiku with an adjustable effort setting — the ability to trade cost against intelligence on the same request instead of switching model tiers. Conceptually it slots into the escalation pattern from our frontier models guide as a middle rung: cheap model at low effort for routine turns, cheap model at higher effort when the task needs thinking, frontier model only when an objective check fails. The full treatment of what effort levels cost is in reasoning effort levels: what thinking budgets cost.
The rest of the announcement: Sonnet cache reads and API credits#
Two changes that aren't about Haiku but matter to the same developers:
- Sonnet 5.5 cache reads halved: $0.20 → $0.10 per million. Cache reads dominate token spend in agentic work, so Anthropic says this cuts the cost of running Sonnet 5.5 on most agentic tasks by around 20%.
- Monthly API credits for Max and Team subscribers, rolling out the week of launch: Max 5x gets $100/month, Max 20x gets $200/month, Team gets up to $500 pooled across users — usable on any Anthropic model. That's a free on-ramp to try Haiku 5.5 (and everything else) on the official platform.
Worked example: what a summarization pipeline costs now#
Take a realistic job: 1,000 documents a day, each needing 8,000 input tokens and producing 500 output tokens. These are assumptions to show the arithmetic — replace them with your own figures.
| Haiku 4.5 | Haiku 5.5 (cheap tier) | |
|---|---|---|
| Per document: 0.008M in | $0.0080 | $0.0008 |
| Per document: 0.0005M out | $0.0025 | $0.00025 |
| Per document total | $0.0105 | $0.00105 |
| Per day (1,000 docs) | $10.50 | $1.05 |
| Per month (22 working days) | about $231 (about ৳28,400) | about $23 (about ৳2,800) |
Remember Anthropic's ~75% average figure when sizing real budgets — the list-price math above is the best case, and your workload's tier mix and tokenizer differences will land somewhere between. Use the method in how to estimate your monthly token bill with your own token counts before committing.
Should you switch?#
- Running Haiku 4.5 for classification, summarization, extraction, or subagent work: switch. It's a one-line model change on the same API, and the price/performance move is one-directional.
- Running GPT-6 Luna for cheap work: Haiku 5.5 now matches its $0.10/$0.50 price point and outscores it on the one shared benchmark (GDPval-AA v2.1: 1620 vs 1437). Try both head-to-head on your own evals.
- Long-context workloads: mind the 100K cliff — chunk, cache, or budget at the upper tier.
- Complex agentic coding: stay on Sonnet 5.5 (now cheaper to run thanks to the cache-read cut) or Opus 5.5.
- On tokens.bd: Haiku 5.5 is not yet in the catalog (checked 8 October 2026 — 62 models listed). The closest cheap alternative in the catalog today is GPT-6 Luna at $0.11/$0.55 per 1M tokens. Check
/modelsfor Haiku 5.5's arrival.
Switching on the Anthropic API is a model-ID change:
from anthropic import Anthropic

client = Anthropic()  # same client, same key
response = client.messages.create(
    model="claude-haiku-5-5",  # was "claude-haiku-4-5-20251001"
    max_tokens=4096,
    messages=[{"role": "user", "content": "Summarize this support thread."}],
)
Prefer the OpenAI SDK? The same one-base_url-change pattern works — see OpenAI vs Anthropic API formats.
Claude Haiku 5.5 FAQ#
How much does Claude Haiku 5.5 cost? $0.10 per million input tokens and $0.50 per million output tokens for prompts up to 100,000 tokens (cache reads $0.01/1M); above 100K tokens the rates are $0.50/$2.50 with $0.05/1M cache reads. That's a 90% list-price cut versus Haiku 4.5's $1.00/$5.00.
Is Claude Haiku 5.5 available on tokens.bd? Not yet — checked 8 October 2026, the catalog lists 62 models and Haiku 5.5 isn't among them. The closest cheap option in the catalog right now is GPT-6 Luna at $0.11/$0.55 per million tokens.
Does Haiku 5.5 replace Sonnet 5.5 for coding? No. Anthropic positions Haiku as the fast, cheap worker tier — classification, summarization, subagent and browser-use tasks — while Sonnet 5.5 and Opus 5.5 remain the picks for complex agentic coding. Haiku 5.5's Terminal-Bench score (39.2%) is a huge jump from Haiku 4.5's 0.0%, but Sonnet still leads on knowledge work.
What is the 100K-token pricing cliff? Requests over 100,000 tokens are billed at 5x the cheap-tier rates ($0.50/$2.50 per million instead of $0.10/$0.50). Since ~90% of Haiku 4.5 requests fell under 100K tokens, most workloads stay cheap — but long-context jobs should chunk, cache (see prompt caching explained), or budget at the upper tier.
Is Haiku 4.5 being retired? The launch announcement did not include a retirement date for Haiku 4.5. Given Sonnet 4.5's retirement on 30 November 2026, it's worth watching Anthropic's deprecation notices — but nothing has been announced for Haiku 4.5.
Prices checked 8 October 2026. Promotional prices change; the maker's page is the authority for list prices, and the model catalog for prices on Tokens. USD→BDT conversions use ~৳123 per USD (8 October 2026).
Sources: Anthropic via Unite.AI · Startup Fortune · VentureBeat · TestingCatalog · OfficeChai