TL;DR — Checked 9 November 2026: Gemini API pricing in November 2026 runs from $0.10 per million input tokens (Gemini 2.5 Flash-Lite) to $2.00 in / $10.00 out (Gemini 4 Argon), and the cheapest current-generation model is Gemini 3.1 Flash-Lite at $0.25/$1.50. Two price doublings are already scheduled: Argon doubles to $4/$20 on 1 December 2026, and Gemini 3.8 Flash doubles to $1.50/$7.50 on 1 January 2027. A heavy coding session (1M input + 100K output tokens) costs $1.13 (≈৳140) on 3.8 Flash and $3.00 (≈৳373) on Argon — and the free tier covers every Flash model except Argon. All prices below are Google's list prices, converted at $1 = 124.35 BDT.
There is a new flagship (Gemini 4 Argon), a new default Flash (Gemini 3.8 Flash), two price increases already dated, and two old models being switched off on 1 December.
What is Gemini API pricing per model?#
Every current Gemini text model costs $0.10–$2.00 per million input tokens and $0.40–$12.00 per million output tokens — but two models charge more for prompts over 200,000 tokens, and three sit on dated intro prices that double soon. Full list, Standard tier; BDT at $1 = 124.35.
| Model | Status | Input / 1M tokens | Output / 1M tokens | Cached input / 1M | Free tier |
|---|---|---|---|---|---|
| Gemini 4 Argon | Current flagship | $2.00 (৳248.70), → $4.00 (৳497.40) from 1 Dec 2026 | $10.00 (৳1,243.50), → $20.00 (৳2,487.00) from 1 Dec 2026 | $0.10 → $0.20 | No |
| Gemini 3.8 Flash | Current Flash | $0.75 (৳93.26), → $1.50 (৳186.52) from 1 Jan 2027 | $3.75 (৳466.31), → $7.50 (৳932.62) from 1 Jan 2027 | $0.075 → $0.15 | Yes |
| Gemini 3.6 Flash | Previous Flash | $0.75 (৳93.26), → $1.50 (৳186.52) from 1 Jan 2027 | $3.75 (৳466.31), → $7.50 (৳932.62) from 1 Jan 2027 | $0.075 → $0.15 | Yes |
| Gemini 3.5 Flash-Lite | Budget workhorse | $0.30 (৳37.30) | $2.50 (৳310.88) | $0.03 | Yes |
| Gemini 3.1 Flash-Lite | Cheapest current | $0.25 (৳31.09) | $1.50 (৳186.52) | $0.025 | Yes |
| Gemini 3.1 Pro Preview | Preview Pro | $2.00 (৳248.70), $4.00 (৳497.40) over 200K-token prompts | $12.00 (৳1,492.20), $18.00 (৳2,238.30) over 200K-token prompts | $0.20 / $0.40 | No |
| Gemini 2.5 Pro | Deprecated | $1.25 (৳155.44), $2.50 (৳310.88) over 200K-token prompts | $10.00 (৳1,243.50), $15.00 (৳1,865.25) over 200K-token prompts | $0.125 / $0.25 | Yes |
| Gemini 2.5 Flash | Deprecated | $0.30 (৳37.30), $1.00 audio | $2.50 (৳310.88) | $0.03 | Yes |
| Gemini 2.5 Flash-Lite | Legacy, not deprecated | $0.10 (৳12.44), $0.30 audio | $0.40 (৳49.74) | $0.01 | Yes |
Prices checked 9 November 2026.
Three things deserve a second look. First, output dominates a real bill: Argon's output costs five times its input, 3.8 Flash's ratio is also five-to-one, and thinking tokens bill at the output rate. Second, the over-200K tier on 2.5 Pro and 3.1 Pro Preview is easy to miss: a 1M-token prompt on 2.5 Pro bills at $2.50/$15.00, not the $1.25/$10.00 headline rate. Third, Gemini 4 Carbon has no row here — Google's pricing page lists no price for it, since access is still gated to cyber defenders. Our Gemini 4 Carbon guide covers what is known.
Two models you might expect are absent, and the absence is the finding. Google's pricing and models pages list no Gemini 3.7 Flash — the current Flash generation is 3.8. A gemini-3.7-flash id does exist on tokens.bd's catalog (see the gateway section below), but it is a gateway-routed id, not a model on Google's official list.
What does a coding session actually cost on Gemini?#
A per-million price means little until you multiply it by a real workload. A standard coding session is 200,000 input tokens and 20,000 output tokens; a heavy agentic session is 1,000,000 input tokens and 100,000 output tokens. Costs below use $1 = 124.35 BDT.
| Model | Standard session (200K in + 20K out) | Heavy session (1M in + 100K out) | 20 heavy sessions / month |
|---|---|---|---|
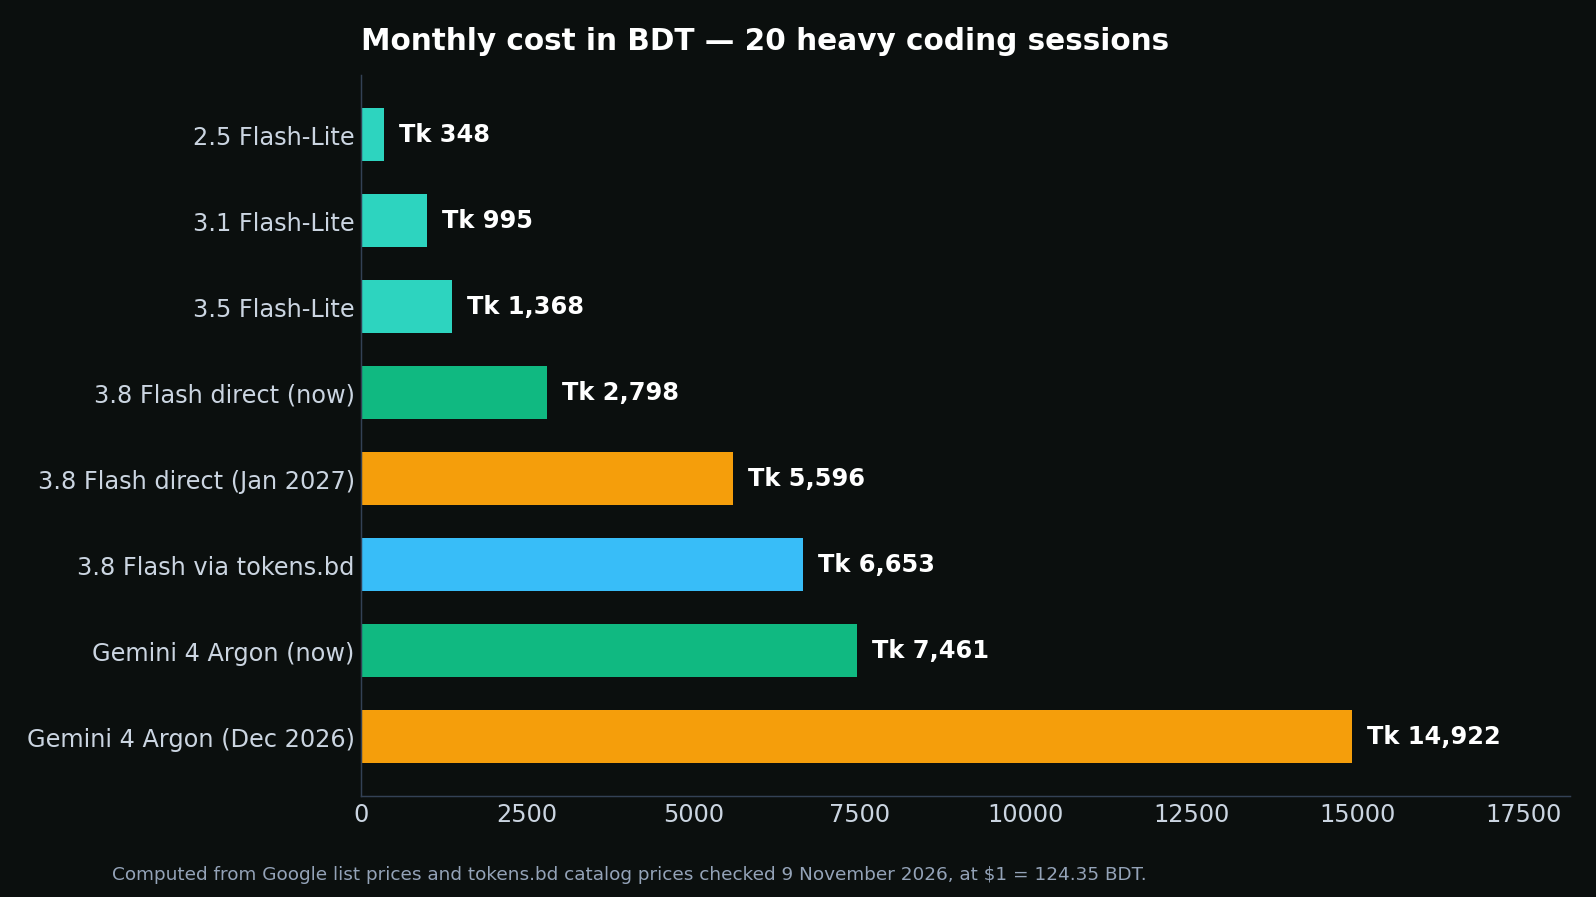
| Gemini 4 Argon (to 30 Nov 2026) | $0.60 (৳74.61) | $3.00 (৳373.05) | $60.00 (৳7,461.00) |
| Gemini 4 Argon (from 1 Dec 2026) | $1.20 (৳149.22) | $6.00 (৳746.10) | $120.00 (৳14,922.00) |
| Gemini 3.8 Flash (to 31 Dec 2026) | $0.23 (৳27.98) | $1.13 (৳140) | $22.50 (৳2,797.88) |
| Gemini 3.8 Flash (from 1 Jan 2027) | $0.45 (৳55.96) | $2.25 (৳279.79) | $45.00 (৳5,595.75) |
| Gemini 3.6 Flash (to 31 Dec 2026) | $0.23 (৳27.98) | $1.13 (৳140) | $22.50 (৳2,797.88) |
| Gemini 3.5 Flash-Lite | $0.11 (৳13.68) | $0.55 (৳68.39) | $11.00 (৳1,367.85) |
| Gemini 3.1 Flash-Lite | $0.08 (৳9.95) | $0.40 (৳49.74) | $8.00 (৳994.80) |
| Gemini 3.1 Pro Preview | $0.64 (৳79.58) | $5.80 (৳721.23) | $116.00 (৳14,424.60) |
| Gemini 2.5 Pro (deprecated) | $0.45 (৳55.96) | $4.00 (৳497.40) | $80.00 (৳9,948.00) |
| Gemini 2.5 Flash (deprecated) | $0.11 (৳13.68) | $0.55 (৳68.39) | $11.00 (৳1,367.85) |
| Gemini 2.5 Flash-Lite | $0.03 (৳3.48) | $0.14 (৳17.41) | $2.80 (৳348.18) |
Checked 9 November 2026, at $1 = 124.35 BDT. Heavy sessions use the over-200K tier; standard sessions the under-200K tier.
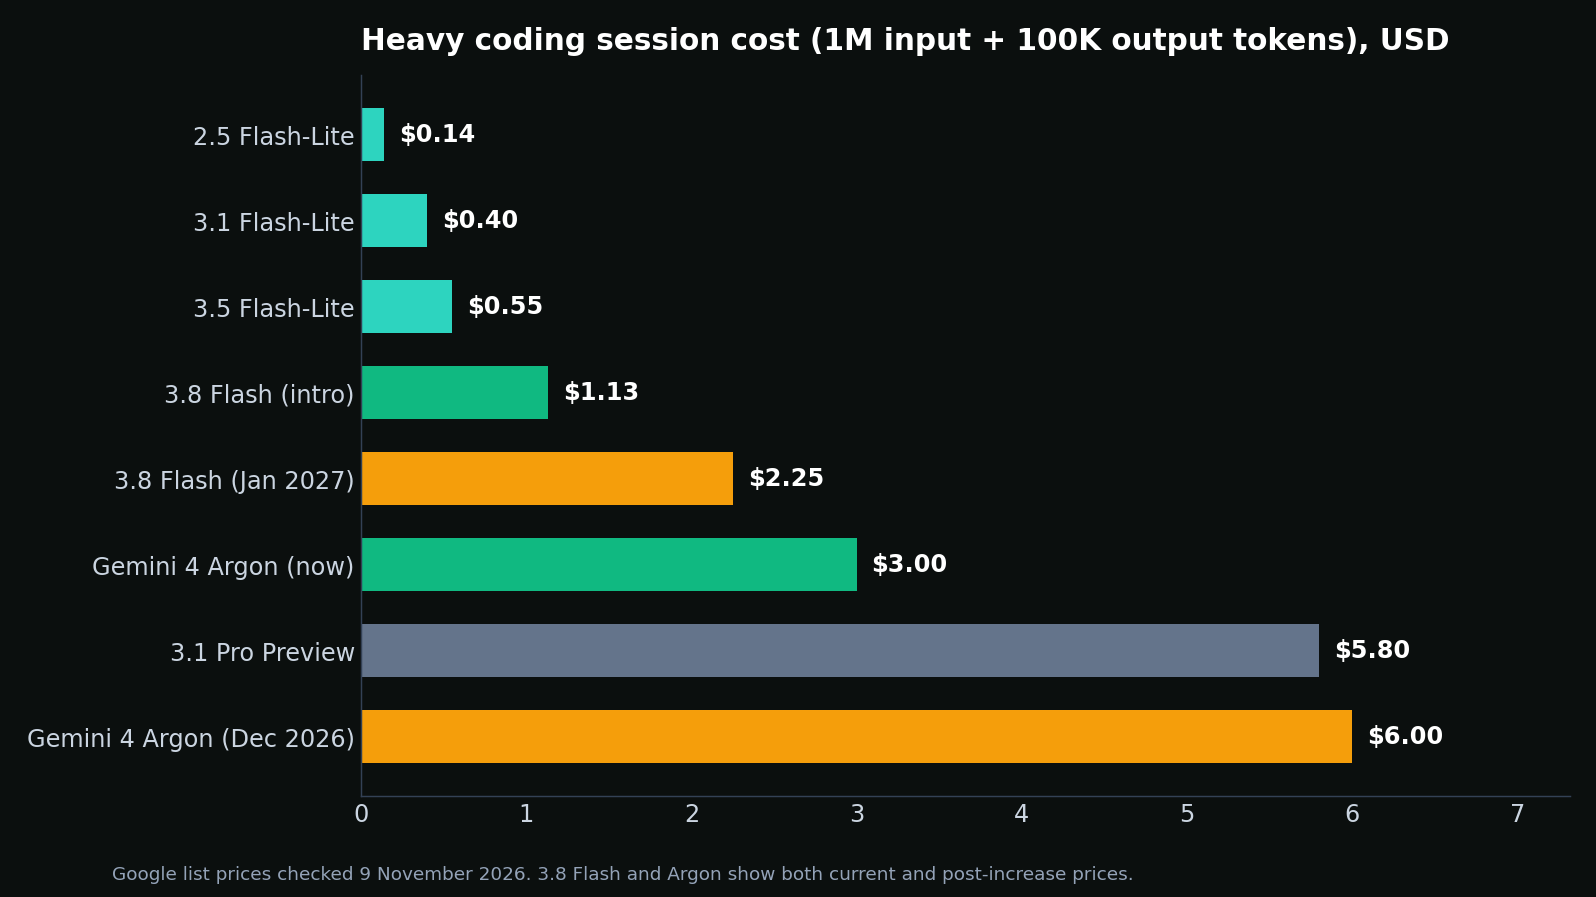
The spread is the story: the most expensive heavy session here (3.1 Pro Preview at $5.80) costs 41 times the cheapest (2.5 Flash-Lite at $0.14), and flagship Argon at $3.00 costs 7.5 times the cheapest current-generation model, 3.1 Flash-Lite at $0.40. Twenty heavy sessions a month costs $8.00 on 3.1 Flash-Lite and $60.00 on Argon — $120.00 after the doubling.
One correction to our own earlier math: our 3 November post priced a heavy 2.5 Pro session at $2.25, using the under-200K tier. A 1M-token prompt is over 200K tokens, so the correct price is $4.00 — the reroute to 3.8 Flash is a 72% cut, not 50%.
What is free on the Gemini API?#
The Gemini API has a genuine free tier — free input and output tokens, not just a trial credit — on every Flash model and the 2.5 family, but not on Argon or 3.1 Pro Preview, which are paid-only. Free-tier prompts may be used to improve Google's products; paid-tier prompts are not.
| Model | Free tier? | What is free |
|---|---|---|
| Gemini 3.8 Flash | Yes | Input, output, caching |
| Gemini 3.6 Flash | Yes | Input, output, caching |
| Gemini 3.5 Flash-Lite | Yes | Input and output tokens |
| Gemini 3.1 Flash-Lite | Yes | Input and output tokens |
| Gemini 2.5 Pro | Yes | Input and output tokens (deprecated, reroutes 1 Dec) |
| Gemini 2.5 Flash | Yes | Input and output tokens (deprecated, reroutes 1 Dec) |
| Gemini 2.5 Flash-Lite | Yes | Input and output tokens |
| Gemini 4 Argon | No | — |
| Gemini 3.1 Pro Preview | No | — |
Free-tier availability checked 9 November 2026.
The honest part is what this table cannot show: Google no longer publishes fixed per-model free-tier rate limits (requests per minute, tokens per minute, requests per day) — the limits are set per project and shown in Google AI Studio, and Google says they are "not guaranteed". What Google does publish is the structure: limits are per project, not per API key; daily quotas reset at midnight Pacific time; spend caps apply once you pay — Tier 1 at $10 per 10 minutes, Tiers 2 and 3 at $200. Tier 1 starts when you link a billing account ($250 cap); Tier 2 after $100 paid plus 3 days; Tier 3 after $1,000 paid plus 30 days. Grounding with Google Search adds 5,000 free requests a month, then $14 per 1,000, capped at 1,500 a day.
Which Gemini prices are about to double?#
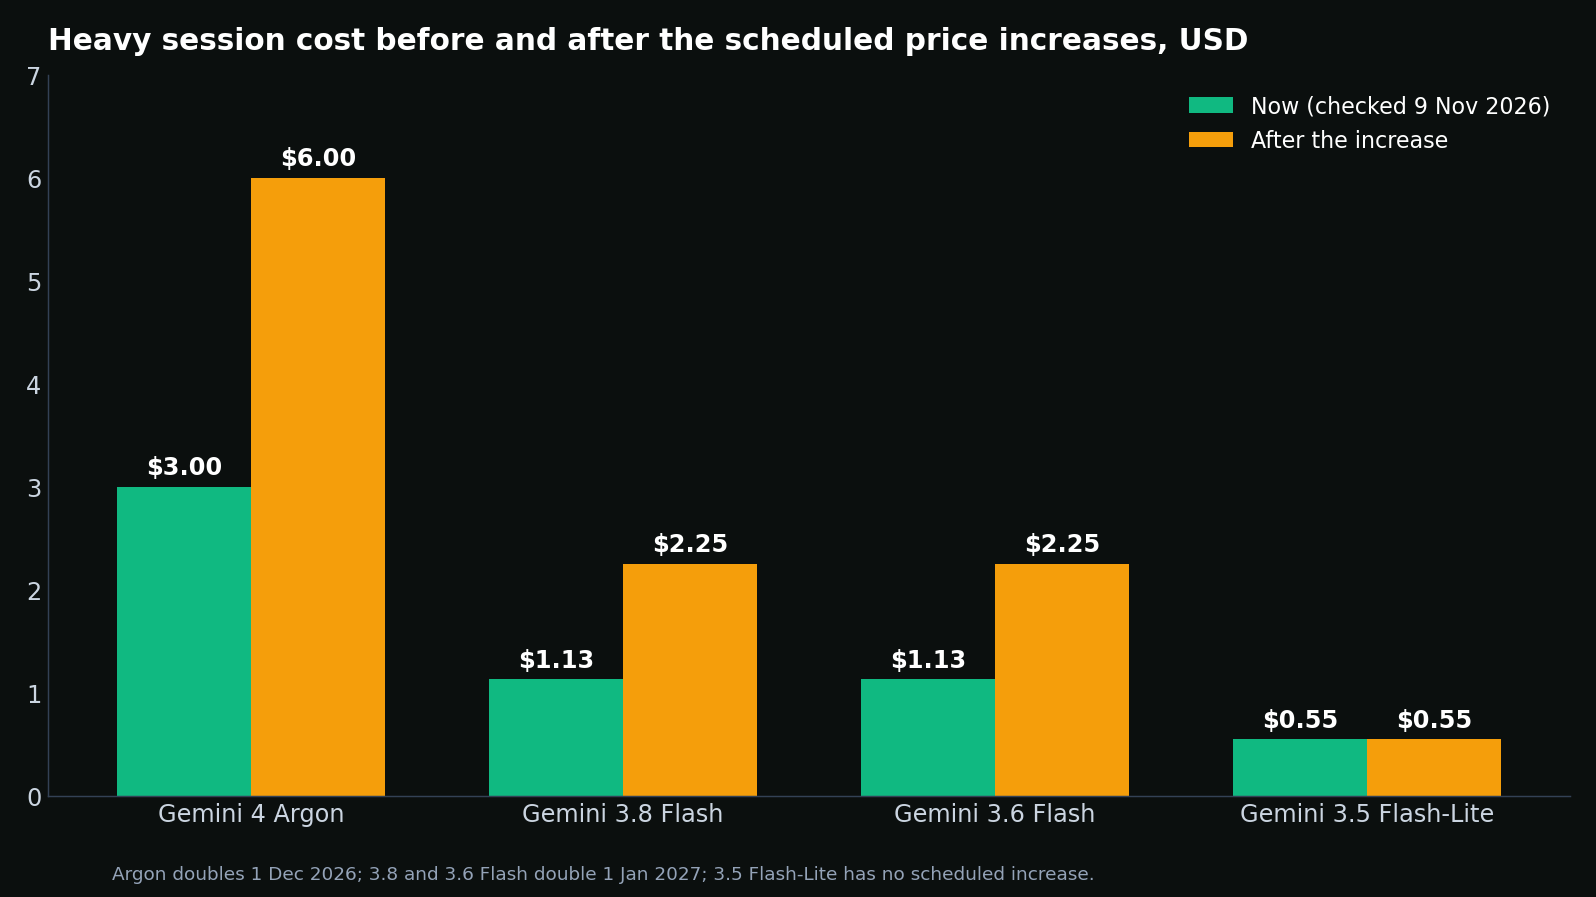
Two dated price increases are already on Google's pricing page. Argon doubles on 1 December 2026; the two current Flash models double on 1 January 2027. Prices checked 9 November 2026.
| Model | Increase date | Input now → then | Output now → then | Heavy session now → then |
|---|---|---|---|---|
| Gemini 4 Argon | 1 December 2026 | $2.00 → $4.00 | $10.00 → $20.00 | $3.00 → $6.00 |
| Gemini 3.8 Flash | 1 January 2027 | $0.75 → $1.50 | $3.75 → $7.50 | $1.13 → $2.25 |
| Gemini 3.6 Flash | 1 January 2027 | $0.75 → $1.50 | $3.75 → $7.50 | $1.13 → $2.25 |
Argon's increase is the urgent one: 1 December is 22 days away, and it doubles everything — input, output, and cached input ($0.10 to $0.20). The Batch API, which bills at half the Standard rate, doubles with it (heavy session $1.50 to $3.00). If your workload genuinely needs Argon, use the intro price hard in November and re-evaluate on 1 December, when Argon at $4/$20 matches Claude Opus 5.5's list price ($4/$20). The Flash increase is less urgent but larger in absolute monthly terms: 3.8 Flash is the default model, so its doubling on 1 January 2027 doubles the bill of every team that standardized on it. Budget January on the $1.50/$7.50 rates, and test whether 3.5 Flash-Lite at $0.30/$2.50 can carry your 3.8 Flash workloads.
What happens to Gemini 2.5 on 1 December 2026?#
Google deprecated gemini-2.5-pro and gemini-2.5-flash on 2 November 2026, and from 1 December 2026 every API request to those model ids automatically routes to a newer model and bills at the new model's rates. The reroutes, re-verified today:
| Your old model id | From 1 December 2026 it runs as | Billed at | Heavy session before → after |
|---|---|---|---|
gemini-2.5-pro | gemini-3.8-flash | Gemini 3.8 Flash rates | $4.00 → $1.13 (intro) |
gemini-2.5-flash | gemini-3.5-flash-lite | Gemini 3.5 Flash-Lite rates | $0.55 → $0.55 |
Deprecation and reroute details checked 9 November 2026.
For Pro users the reroute is a gift with an expiry date: the heavy session drops from $4.00 to $1.13 while 3.8 Flash holds its intro price, then rises to $2.25 on 1 January 2027 — still below the $4.00 Pro cost. For Flash users it is price-neutral: both models cost $0.55 a heavy session. The one model that does not move is gemini-2.5-flash-lite: not deprecated, still served, limited to existing users. What else breaks — thinking controls, sampling parameters, prefilled turns, function calling — is in our Gemini 2.5 deprecation checklist.
How do I cut my Gemini bill in half?#
Three levers, in order of savings. First, context caching: cached input on 3.8 Flash costs $0.075 per million tokens against $0.75 fresh. With 80% of a standard session's input served from cache, the session falls from $0.225 to $0.117 — a 48% saving with no model change. Caching is per model. Second, the Batch API: asynchronous requests bill at exactly half the Standard rate — a heavy 3.8 Flash session drops from $1.13 to $0.56 — the right choice for anything that can wait minutes. Third, downgrading one tier: a heavy session costs $1.13 on 3.8 Flash, $0.55 on 3.5 Flash-Lite, and $0.40 on 3.1 Flash-Lite, so workloads that do not need the stronger model save 51% to 65% by moving down.
What does Gemini cost through tokens.bd?#
If you are in Bangladesh, the direct Google route has a payment problem: it needs an international card. tokens.bd's catalog, checked live today, lists two Gemini models — google/gemini-3.8-flash at $1.80/$8.75 per million tokens and google/gemini-3.7-flash at $1.80/$9.00 — both on Weekly, Monthly, and pay-as-you-go, with BDT payment. Note: gemini-3.7-flash appears only on tokens.bd — Google's own pages list no such model. Argon and Carbon are not on tokens.bd.
| Route | Per-1M input / output | Heavy session | 20 heavy sessions / month |
|---|---|---|---|
| Direct, Gemini 3.8 Flash (intro, to 31 Dec 2026) | $0.75 / $3.75 | $1.13 (৳140) | $22.50 (৳2,797.88) |
| Direct, Gemini 3.8 Flash (standard, from 1 Jan 2027) | $1.50 / $7.50 | $2.25 (৳279.79) | $45.00 (৳5,595.75) |
| tokens.bd, Gemini 3.8 Flash | $1.80 / $8.75 | $2.68 (৳333) | $53.50 (৳6,652.72) |
| tokens.bd, Gemini 3.7 Flash | $1.80 / $9.00 | $2.70 (৳336) | $54.00 (৳6,714.90) |
Catalog prices checked 9 November 2026.
The honest comparison: tokens.bd's 3.8 Flash costs 2.4 times Google's direct intro price per heavy session ($2.68 against $1.13) — the gateway charges for BDT payment, one key across 60+ models, and per-key spend caps, not for a cheaper Gemini bill. If your workload is Gemini-only and you can pay Google directly, direct is cheaper until the intro ends; after 1 January, when direct 3.8 Flash rises to $2.25 a session, the gap narrows to $2.68 against $2.25. Plan math: Weekly 5X costs ৳90 a week with $10 in credits included (up to ~$20 of usage with deals); Monthly Max costs ৳490 a month with $50 in credits (up to ~$60 with deals).
from openai import OpenAI

client = OpenAI(
    base_url="https://tokens.bd/v1",
    api_key="YOUR_TOKENS_BD_KEY",
)

response = client.chat.completions.create(
    model="google/gemini-3.8-flash",
    messages=[{"role": "user", "content": "Explain this diff and suggest a fix."}],
)
print(response.choices[0].message.content)
If Gemini is not the cheapest route for your task, the same key reaches cheaper heavy sessions elsewhere — Claude Haiku 5.5 at $0.15 (≈৳19), GPT-6 Luna at $0.21 (≈৳26), GLM-5.3 Flash at $0.23 (≈৳28), and DeepSeek V4.1 Flash 1017 at $0.38 (≈৳47) — all verified against the catalog today. Eval them before switching.
Which Gemini model should I pick?#
A ranked list, cheapest-first by job rather than by price alone:
- Gemini 3.8 Flash — the default. Google's most intelligent Flash model, 1M-token context, built for long-horizon coding and agents. Lock in the intro price before it doubles on 1 January 2027.
- Gemini 3.5 Flash-Lite — the volume pick. $0.30/$2.50, no scheduled price increase, tuned for high-throughput agentic tasks. Use it for bulk work and subagents.
- Gemini 3.1 Flash-Lite — the cheapest current model. $0.25/$1.50, a heavy session for $0.40. Use it where latency and cost dominate.
- Gemini 4 Argon — the hard-problem pick, before 1 December only. The flagship reasoning model, 1M context, at $2/$10 until 30 November. Use it for the hardest reasoning in November, then re-evaluate: at $4/$20 from 1 December it matches Claude Opus 5.5.
- Gemini 3.1 Pro Preview — only with eyes open. $2/$12 under 200K-token prompts, $4/$18 over, no free tier, preview status.
- Avoid: Gemini 2.5 Pro and 2.5 Flash. Deprecated, rerouted on 1 December; 2.5 Pro's heavy session at the over-200K tier costs $4.00 — more than its replacement. Migrate now.
Gemini API pricing FAQ#
Is the Gemini API free? Yes, for most models. Gemini 3.8 Flash, 3.6 Flash, 3.5 Flash-Lite, 3.1 Flash-Lite, and the 2.5 family all have a free tier. Gemini 4 Argon and Gemini 3.1 Pro Preview do not. Free-tier limits are set per project in Google AI Studio, and free-tier prompts may be used to improve Google's products.
How much does Gemini 3.8 Flash cost? $0.75 per million input tokens and $3.75 per million output tokens through 31 December 2026, then $1.50 and $7.50 from 1 January 2027. A heavy session costs $1.13 now and $2.25 from January.
What happens on 1 December 2026?
Two things. Gemini 4 Argon's intro price ends and its price doubles, from $2/$10 to $4/$20 per million tokens. And the reroute takes effect: gemini-2.5-pro runs as gemini-3.8-flash and gemini-2.5-flash as gemini-3.5-flash-lite, billed at the new models' rates.
What is the cheapest Gemini model? Gemini 2.5 Flash-Lite at $0.10/$0.40 per million tokens, but it is a legacy model limited to existing users. The cheapest current-generation model is Gemini 3.1 Flash-Lite at $0.25/$1.50, with a heavy session costing $0.40 (≈৳50). For most workloads the practical cheapest is 3.5 Flash-Lite at $0.55 a session.
Can I pay for Gemini in BDT? Yes, through tokens.bd: Gemini 3.8 Flash lists at $1.80/$8.75 and Gemini 3.7 Flash at $1.80/$9.00 per million tokens, on Weekly 5X (৳90/week) and Monthly Max (৳490/month) or pay-as-you-go, with no international card. The gateway costs more per Gemini session than Google's direct intro price; the value is BDT payment, one key across 60+ models, and per-key spend caps.
All prices checked 9 November 2026. Google's pricing page is the authority for list prices; the model catalog for tokens.bd prices.
Sources: Google Gemini Developer API pricing · Google Gemini models · Gemini 3.8 Flash model page · Gemini 3.6 Flash model page · Gemini 3.5 Flash-Lite model page · Google Gemini API rate limits · tokens.bd models · tokens.bd pricing · USD to BDT mid-market rate, 9 November 2026