OpenAI Prompt Caching: What It Actually Saves You (2026)
OpenAI's prompt caching is automatic — cached input costs 50–95% less depending on the model. How it works, what each model saves, and the math. Checked 16 October 2026.
4 Uncensored LLM model added, currently available for only pay-as-you-go users.See Models

OpenAI's prompt caching is automatic — cached input costs 50–95% less depending on the model. How it works, what each model saves, and the math. Checked 16 October 2026.

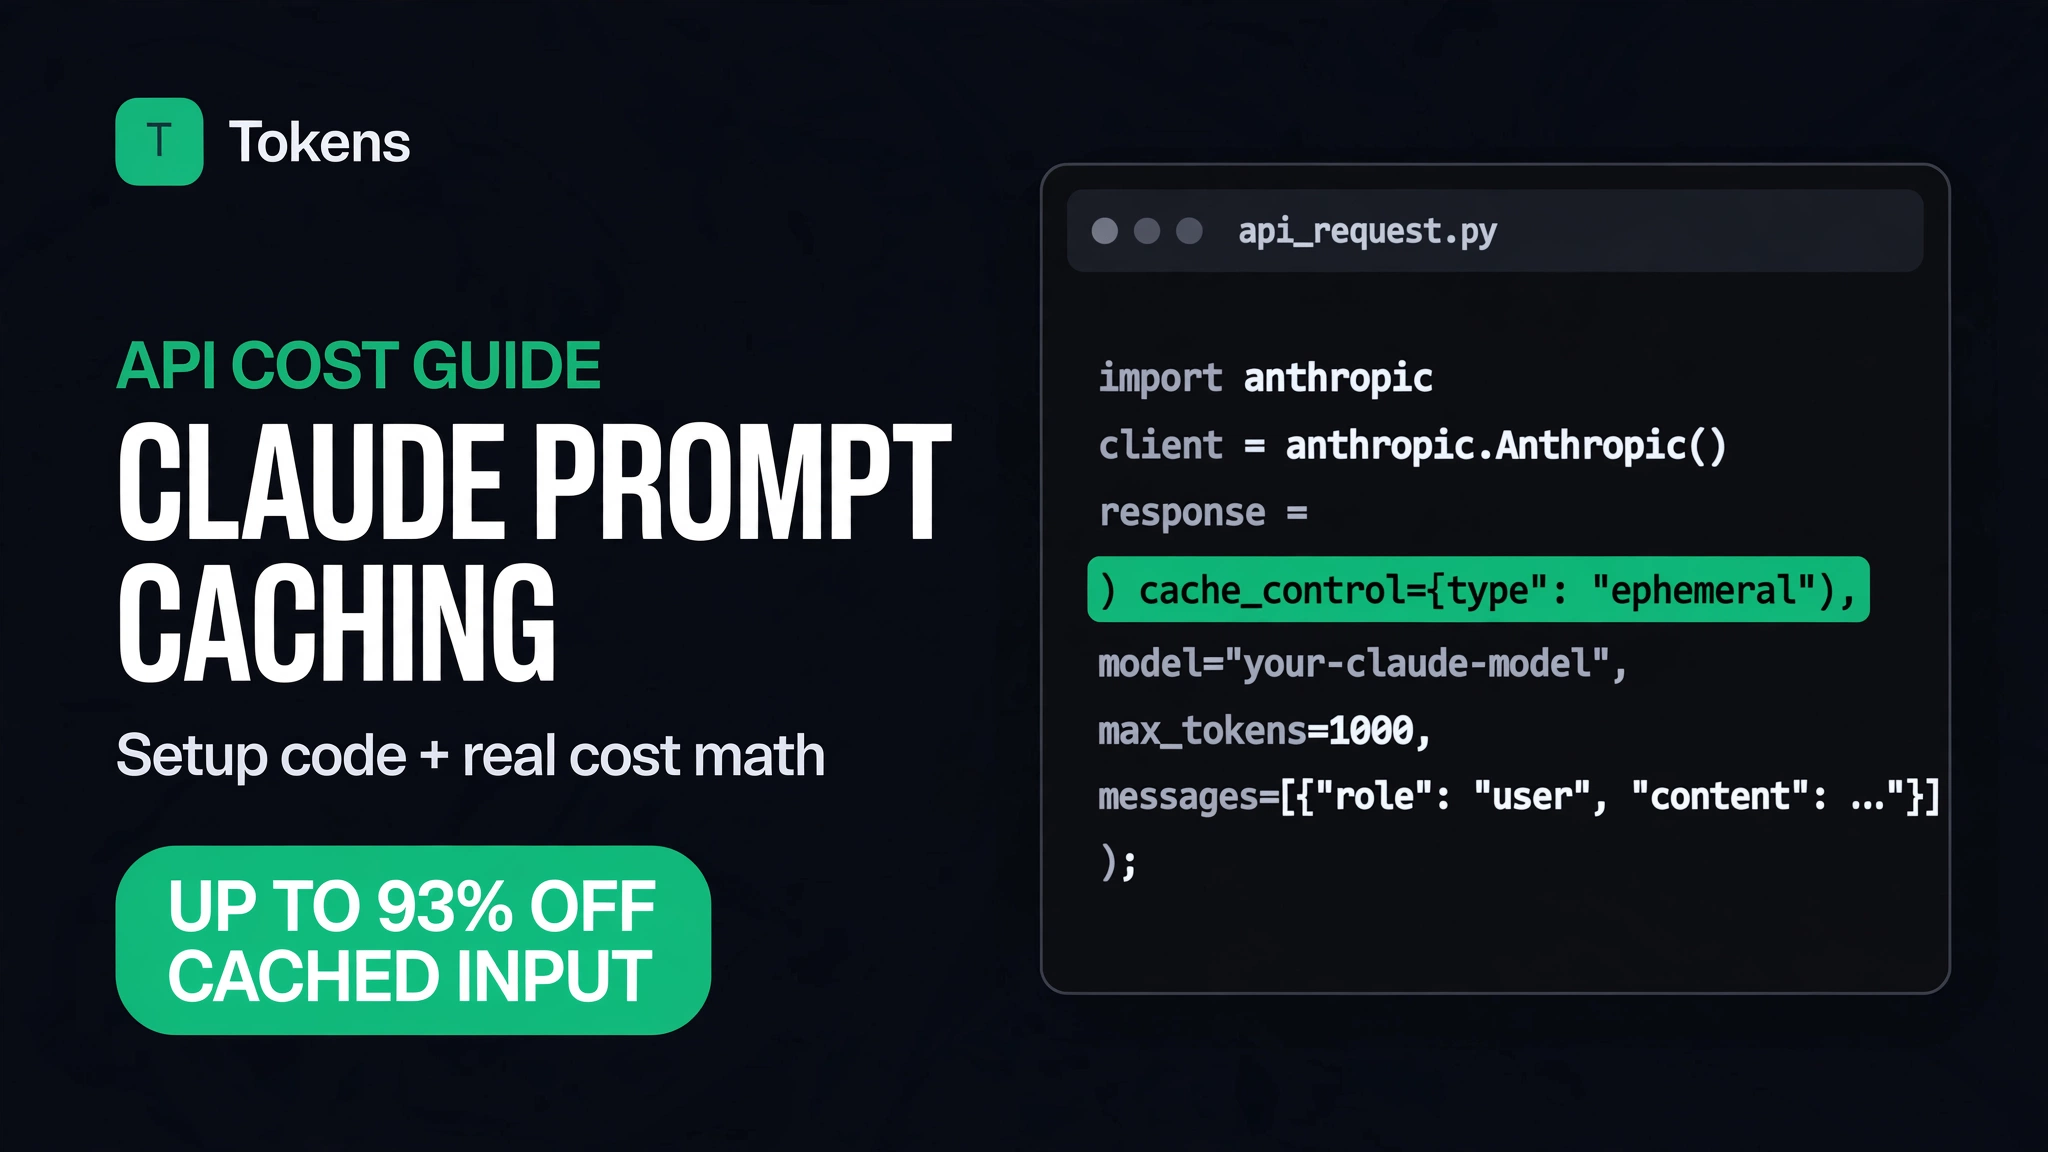
Turn on Claude prompt caching with automatic or breakpoint mode, verify hits in the usage object, and run the real Sonnet 5.5 cost math. Prices checked 15 October 2026.
The Tokens CLI writes one key into Claude Code, Codex CLI, OpenCode and Crush in a single run, backs up every file it touches, and can show you the plan first. What each flag does, which files change, and how to wire up Cline, Kilo, Continue and Zed by hand.
Agent loops re-send their whole context every turn, so a stuck one gets expensive fast. How to layer per-key monthly caps, model allow-lists, usage windows and alerts, poll your remaining budget from a script, and recognise the errors when a limit trips.
A field guide to the errors an AI gateway returns, using Tokens' real error codes: which ones mean fix your setup, which mean top up, which mean wait. Plus a retry function that honours Retry-After and never retries a 4xx, and what to put in a support ticket.